VENA PROJECT
VENA
PROJECT
End-to-End MLOps pipeline for predictive healthcare diagnostics.
Clinical Records
Kaggle Stroke Dataset
Handling 95% extreme class imbalance
Built for Production, Not Just Notebooks
A model without a pipeline is just a science experiment. Vena is engineered as a fully reproducible, enterprise-grade machine learning system.
We completely decoupled our data processing, neural network architecture, and training loops into a modular structure, ensuring absolute scalability from local development to cloud deployment.
Hydra Configuration
Zero hardcoding. Every hyperparameter, layer dimension, and training metric is dynamically injected via config files.
Multi-Layer Containerization
Optimized Docker builds with cached dependency layers ensure ultra-fast, independent environments across all machines.
Advanced Model Performance

100%
Fully decoupled MLOps pipeline for instant reproducibility.

<50ms
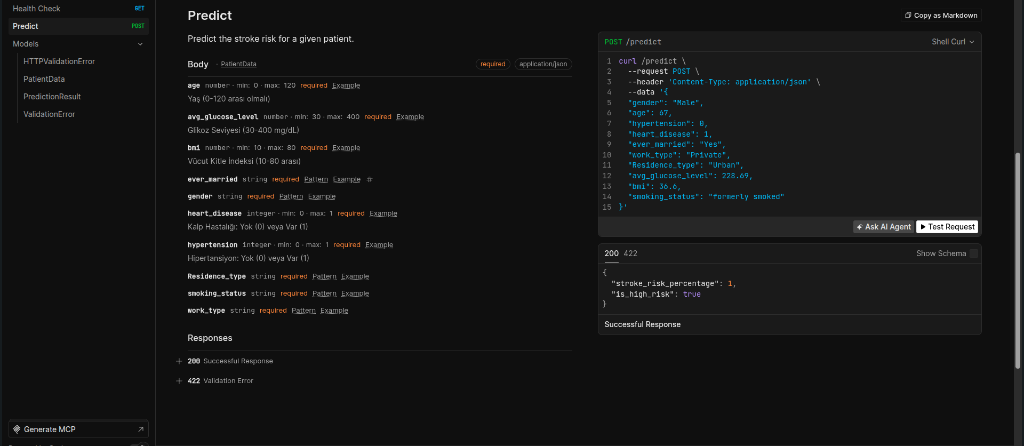
Instant API predictions powered by FastAPI.


95%
AUROC performance achieved through Tabular Deep Learning.
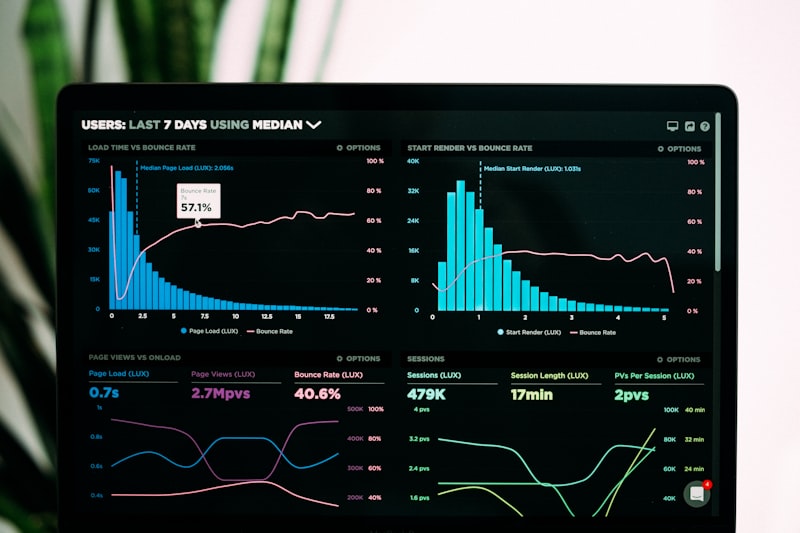
100%
Built entirely on transparent, open-source AI frameworks.
Stroke is the 2nd Leading Cause of Death Globally
15 Million Cases
According to the WHO, 15 million people suffer a stroke annually. 5 million die, and another 5 million are permanently disabled.

Hidden Risk Factors
Many strokes occur suddenly without prior symptoms. Hidden conditions like asymptomatic hypertension and elevated glucose levels drastically increase risk.

80% Are Preventable
Prevention is the best medicine. Deep Learning architectures like Vena can detect complex physiological correlations to catch these risks before they become critical.
Developer Experience First
Interact with Vena API using our beautifully crafted, real-time Scalar API Documentation. Because your inference endpoints deserve a premium interface.
Your Source for Knowledge and Insights
Enter your clinical parameters to receive an instant, AI-driven assessment of your stroke risk profile.